Unleash the Power of XPath Normalize-Space
In the realm of web testing, precision is paramount. Selenium, a widely-used testing framework, provides a range of tools to ensure the accuracy and reliability of test scripts. One such tool is XPath, a powerful language used to navigate and interact with elements on web pages. Among XPath’s array of functions, “normalize-space()” stands out as a valuable asset.
This guide embarks on a journey to unravel the potential of XPath’s normalize-space() function in Selenium test automation. By the end, you’ll be equipped with the expertise to harness normalize-space() for enhanced element identification and text handling.
What is Normalize-Space() in XPath?
XPath’s normalize-space() function is designed to tackle the challenges posed by whitespace within text content. When applied to a string, this function removes leading and trailing spaces, as well as extra spaces between words, ensuring that only a single space remains between words. This is particularly beneficial when dealing with text elements in web pages, as it standardizes the text content for accurate comparison and validation.
Example: Applying Normalize-Space()
Consider a scenario where you’re testing a web form that includes a text field for email addresses. The text input may unintentionally contain extra spaces due to user input errors. Utilizing normalize-space() ensures consistent text comparison, regardless of minor whitespace discrepancies.
WebElement emailField = driver.findElement(By.xpath(“//input[@id=’email’]”));
String expectedEmail = “[email protected]”;
String actualEmail = emailField.getAttribute(“value”);
if (actualEmail.equals(expectedEmail)) {
System.out.println(“Email address is correct.”);
} else {
System.out.println(“Email address is incorrect.”);
}
Harnessing Normalize-Space() for Text Handling
Normalize-space() proves invaluable when dealing with text-based verifications in web testing. Text content retrieved from web elements may unintentionally contain varying amounts of whitespace, making direct comparisons prone to errors. By employing normalize-space(), you can ensure consistent and accurate text validation.
Example: Comparing Text Content
Suppose you’re validating the presence of a welcome message on a web page. The message’s text content might include extra spaces that could lead to false negative results during verification. Normalize-space() resolves this issue:
WebElement welcomeMessage = driver.findElement(By.xpath(“//div[@class=’welcome-msg’]”));
String expectedMessage = “Welcome, User!”;
String actualMessage = welcomeMessage.getText();
if (actualMessage.equals(expectedMessage)) {
System.out.println(“Welcome message is correct.”);
} else {
System.out.println(“Welcome message is incorrect.”);
}
Comparing Normalize-Space() and Text in XPath: Understanding the Distinctions
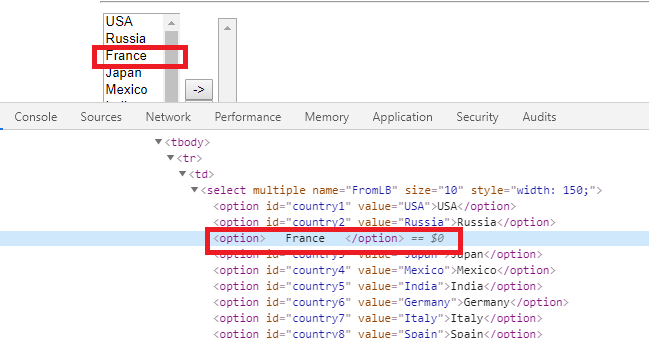
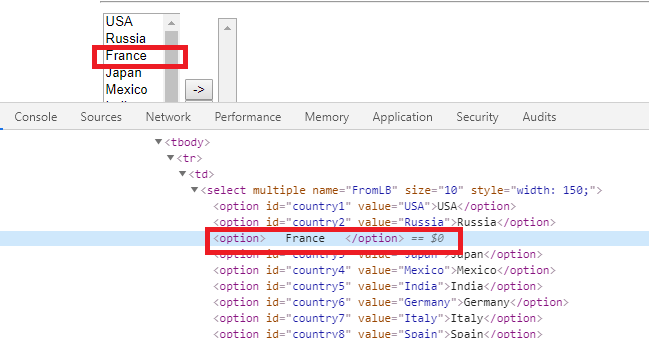
Both normalize-space() and text() functions in XPath are used to retrieve text content from web elements. However, their behavior and applications differ. While text() directly extracts the text as-is, normalize-space() sanitizes the text by removing extra spaces, ensuring consistent and reliable text extraction and comparison.
Example: Differentiating Between Text and Normalize-Space()
Suppose you’re verifying the text content of a paragraph element. The paragraph contains trailing and leading spaces as well as inconsistent spacing between words. Employing both functions provides a clear illustration of their differences:
WebElement paragraph = driver.findElement(By.xpath(“//p[@id=’content’]”));
String expectedText = “This is a paragraph with spaces.”;
String actualText = paragraph.getText();
String normalizedText = driver.findElement(By.xpath(“//p[@id=’content’]”)).getText();
if (actualText.equals(expectedText)) {
System.out.println(“Text comparison is correct.”);
} else {
System.out.println(“Text comparison is incorrect.”);
}
if (normalizedText.equals(expectedText)) {
System.out.println(“Normalized text comparison is correct.”);
} else {
System.out.println(“Normalized text comparison is incorrect.”);
}
Addressing XPath Spaces: Clarifying the Role of Whitespace
In XPath, spaces, including leading, trailing, and consecutive spaces, are treated as regular characters. This means that when writing XPath expressions, you need to be mindful of the spaces within your queries. Utilizing normalize-space() helps alleviate issues caused by inconsistent spaces, making your XPath expressions more reliable.
Exploring Beyond Whitespace: XPath’s Rich Functionality
While XPath’s normalize-space() function shines when it comes to handling whitespace, it’s important to note that XPath offers a plethora of other functions that contribute to powerful web element identification and interaction.
In this video learn more
count() Function: Counting Elements
The count() function allows you to determine the number of elements matching a specific XPath expression. This is particularly useful when you need to verify the presence of a certain number of elements on a page.
List<WebElement> links = driver.findElements(By.xpath(“//a”));
int numberOfLinks = links.size();
System.out.println(“Number of links on the page: ” + numberOfLinks);
contains() Function: Text-Based Searches
The contains() function lets you search for elements containing specific text. This is helpful when you need to identify elements based on their text content, even if the content is not an exact match.
WebElement searchInput = driver.findElement(By.xpath(“//input[contains(@class, ‘search’)]”));
searchInput.sendKeys(“Selenium”);
starts-with() Function: Matching Prefixes
The starts-with() function enables you to locate elements whose attribute values start with a specific substring. This is handy when elements share a common attribute prefix.
WebElement emailField = driver.findElement(By.xpath(“//input[starts-with(@id, ’email’)]”));
emailField.sendKeys(“[email protected]”);
Conclusion
As you conclude this exploration into XPath normalize-space() and its application in Selenium testing, you’re armed with a powerful tool for accurate and consistent web testing. The ability to handle whitespace-related challenges and ensure reliable text comparison is a game-changer in the world of automated testing.
By mastering XPath normalize-space(), you’re enhancing the precision and reliability of your Selenium test scripts. Whether you’re validating text content, verifying data inputs, or interacting with dynamic web elements, normalize-space() empowers you to overcome common challenges and build robust test automation solutions.
As you continue your journey in Selenium test automation, remember that a thorough understanding of XPath functions like normalize-space() is a valuable asset that elevates your ability to navigate, interact, and verify web elements effectively. With your newfound expertise, you’re well-prepared to conquer the complexities of web testing with confidence and finesse.